Jev for SEO: What Worked, What Failed, and What We Measured
Jev is a small AI model from TypeSafe that answers closed questions about a piece of text and attaches a probability to every answer it gives. We put it to work on five SEO jobs across 3,566 AI answers and about 30,000 search queries and keywords, and it held up well wherever it was used as a classifier inside a larger pipeline. Where it fell short the cause was usually the way we had asked the question or the yardstick we had chosen to measure it against.
Key takeaways
- Brand mentions: every one of the 140 "named" verdicts we sampled from Jev was correct, and yet our counts were still about 6% low because of the way a single question had been worded.
- Search intent: across five sites that Jev had never seen it matched a blind reader on about 86% of queries, while a paid intent classifier managed about 48% on a separate set.
- AI fan-out queries: these cannot be verified from the text alone - when two careful readers labelled the same 30 queries they disagreed on 24 of them.
- Rewriting the question helped on some jobs and did nothing on others, which means a new wording has to be tested on fresh data before it can be trusted.
- Agreement with another model misled us twice. It took labels from a reader who could not see any of the answers to show what was really happening.
About the data: these tests draw on 3,566 AI answers and about 30,000 search queries and keywords. Our own site, tenpointlabs.com, supplies 2,944 of the queries and every query quoted in this series. These are the queries Search Console reports for web search between 9 June 2025 and 9 October 2026. They are a sample of our traffic and not all of it, because Search Console leaves out anonymised queries, and no GA4 data is used. The rest comes from client and prospect accounts, which are anonymised - described by industry, never named, and quoted only with the names changed.
Why use AI for SEO this way?
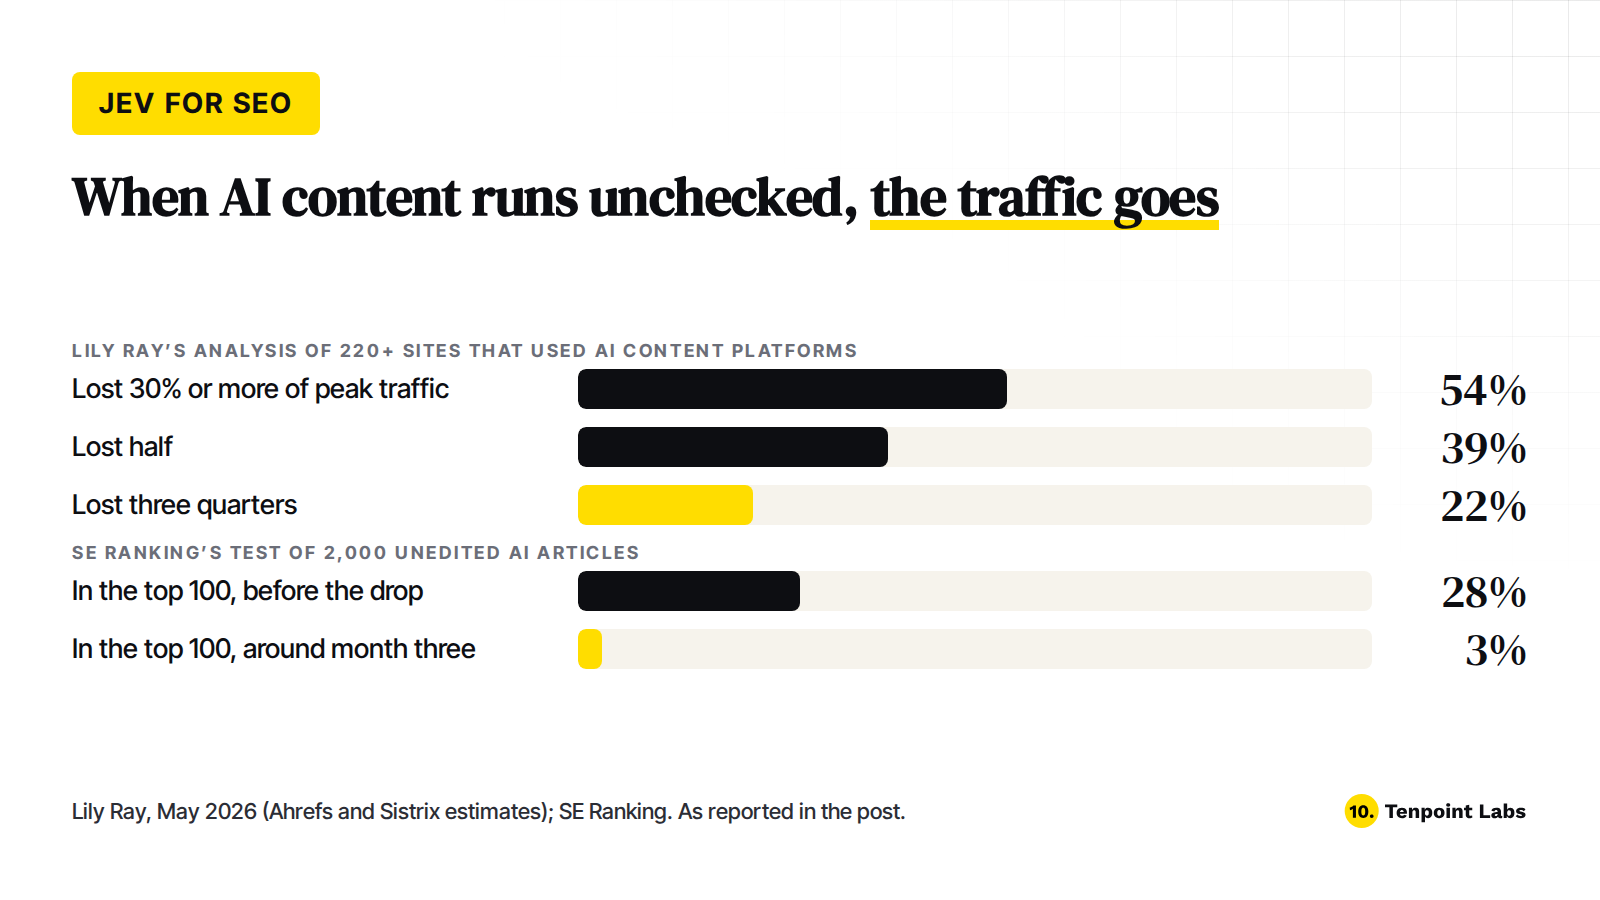
Publishing AI-written content at scale now comes with a documented failure rate. Lily Ray tracked more than 220 sites that AI content platforms had named as customers and in her count 54% had lost 30% or more of their peak organic traffic, 39% had lost half and 22% had lost three quarters (her analysis, May 2026). The figures are Ahrefs and Sistrix estimates and Ray is careful to say that she is describing a pattern across similar sites and is making no claim about any single tool.
Glenn Gabe has given the shape of that traffic chart a name - "Mt. AI". He documented a directory of AI-written local news that had grown to more than 850,000 indexed URLs, and he reports that once Google applied a manual action for scaled content abuse the directory vanished from AI Overviews and AI Mode in his checks and lost most of its ChatGPT citations as well.
SE Ranking ran what amounts to the controlled version of the same story by publishing 2,000 unedited AI articles across 20 new domains. According to its write-up 71% of them were indexed within 36 days, but around the three-month mark the share ranking in the top 100 fell from 28% to 3%.
People keep saying that this shows AI and SEO don't mix. I think this is incorrect. What went wrong in each of these cases was that AI was pointed at the content and left to run with nobody checking what came out. When it is pointed at the data instead - with an expert still making the decisions - it becomes useful in a way that we were able to measure. The process we use for the content itself is set out in how B2B teams use AI content creation without losing rankings.
What is Jev?
Jev is a model from TypeSafe that is currently in early access. It is the first of what TypeSafe calls System One models, which the company describes as "built for decisions inside software". Unlike the large models most marketers are familiar with it does not write text. You send it a piece of text along with a typed question and it returns one of three things:
- A yes-or-no probability, which TypeSafe calls a noul.
- A choice from a list you define, with a probability for each option.
- A score on a scale you define.
TypeSafe lists the current version, jev-1.13.0, at $0.042 per million input tokens with output free. Tenpoint Labs is a TypeSafe customer and has no other relationship with the company.
What did we measure?
Table 1. Jev on five SEO jobs, October 2026. "Reader" means a person or model labelling rows without seeing any method's answer.
| Job | Data | Result | Verdict |
|---|---|---|---|
| Brand mention tracking | 3,566 AI answers, 10 brands | 140 of 140 sampled "named" verdicts correct. About 6% of real mentions lost to a badly worded question | Use it, and ask about the name as written |
| Search intent classification | 1,326 keywords, then 14,902 queries on 5 unseen sites | About 86% against a reader on unseen sites. A paid classifier scored about 48% on the first set | Use it |
| Query fan-out | 7,157 queries, then 14,902 on 5 unseen sites | Flags a similar share to a regex. Readers disagreed too much to score anyone | Use it to describe queries, never to prove who sent them |
| Branded query split | 2,944 queries, our own site | Agreed with a regex on 99.4%, and showed the regex was too loose | Keep the regex |
| Keyword relevance, 16 labels | 2,804 keywords, one site | Roughly level with a much larger model. People disagreed about as much as the models did | Promising, and unproven beyond one site |
Every result here comes from jev-1.13.0 and all of the runs took place between 3 and 9 October 2026.
Which SEO jobs suit Jev, and which don't?
Table 2. SEO use cases for Jev and what we found or expect
| Use case | Status | Verdict |
|---|---|---|
| Brand mentions in AI answers | Tested | Works |
| Search intent labels | Tested | Works |
| Sentiment of a brand mention | Tested on one brand | Roughly level with a larger model |
| Keyword relevance to a product | Tested on one site | Promising |
| Describing query shape (question, instruction, comparison) | Tested | Works |
| Proving a query came from an AI assistant | Tested | No method can, from text |
| Branded and non-branded split | Tested | A regex does it for free |
| Content pruning verdicts | Not tested | We had no fair answer key |
| Word counts, dates, thresholds, deduplication | Reviewed | Keep these as code |
Behind that table sits a simple four-step test that we now run before any job is handed to a tool:
- Can code decide it from the data alone? Then write the rule, which is free and gives the same answer every time.
- Does it depend on facts outside the text? Then it needs a person.
- Is it a closed question about what the text means? That is Jev's job.
- Does the answer need to be written? That needs a general-purpose model.
What went wrong, and whose fault was it?
The bulk of what went wrong was our own doing, and the same three mistakes are likely to be sitting in other teams' setups as well.
We asked about the wrong form of a name. Our search step would find "Acme" for a brand that was stored as "Acme Retail" and then ask Jev whether "Acme Retail" appeared in the passage. Jev said no - which was correct by the letter of the question - and about 6% of real mentions were lost as a result.
We asked for something the text does not contain. Our first fan-out question asked whether an AI had written the query. Jev hedged near 0.5 on almost everything it was shown and only 5 of 7,157 queries reached 0.8.
We scored it against references that were worse than it was. Jev "agreed" with a paid intent classifier on 54.9% of keywords and at first that looked like a failure on Jev's part. A blind reader then sided with Jev on 86 of the 120 disagreements we sampled and with the classifier on only 17.
However some of the limits do belong to the model. It reads questions literally, its answers to identical requests vary slightly from one run to the next, and reversing the order of the options changed 5% to 9% of labels - with nearly all of those on rows where it was already unsure.
How should you handle the answers it isn't sure about?
The probability attached to each answer is the most useful thing Jev returns. In production we count 0.8 or higher as a yes and 0.2 or lower as a no, and anything that falls between the two is sent to a larger model or to a person.
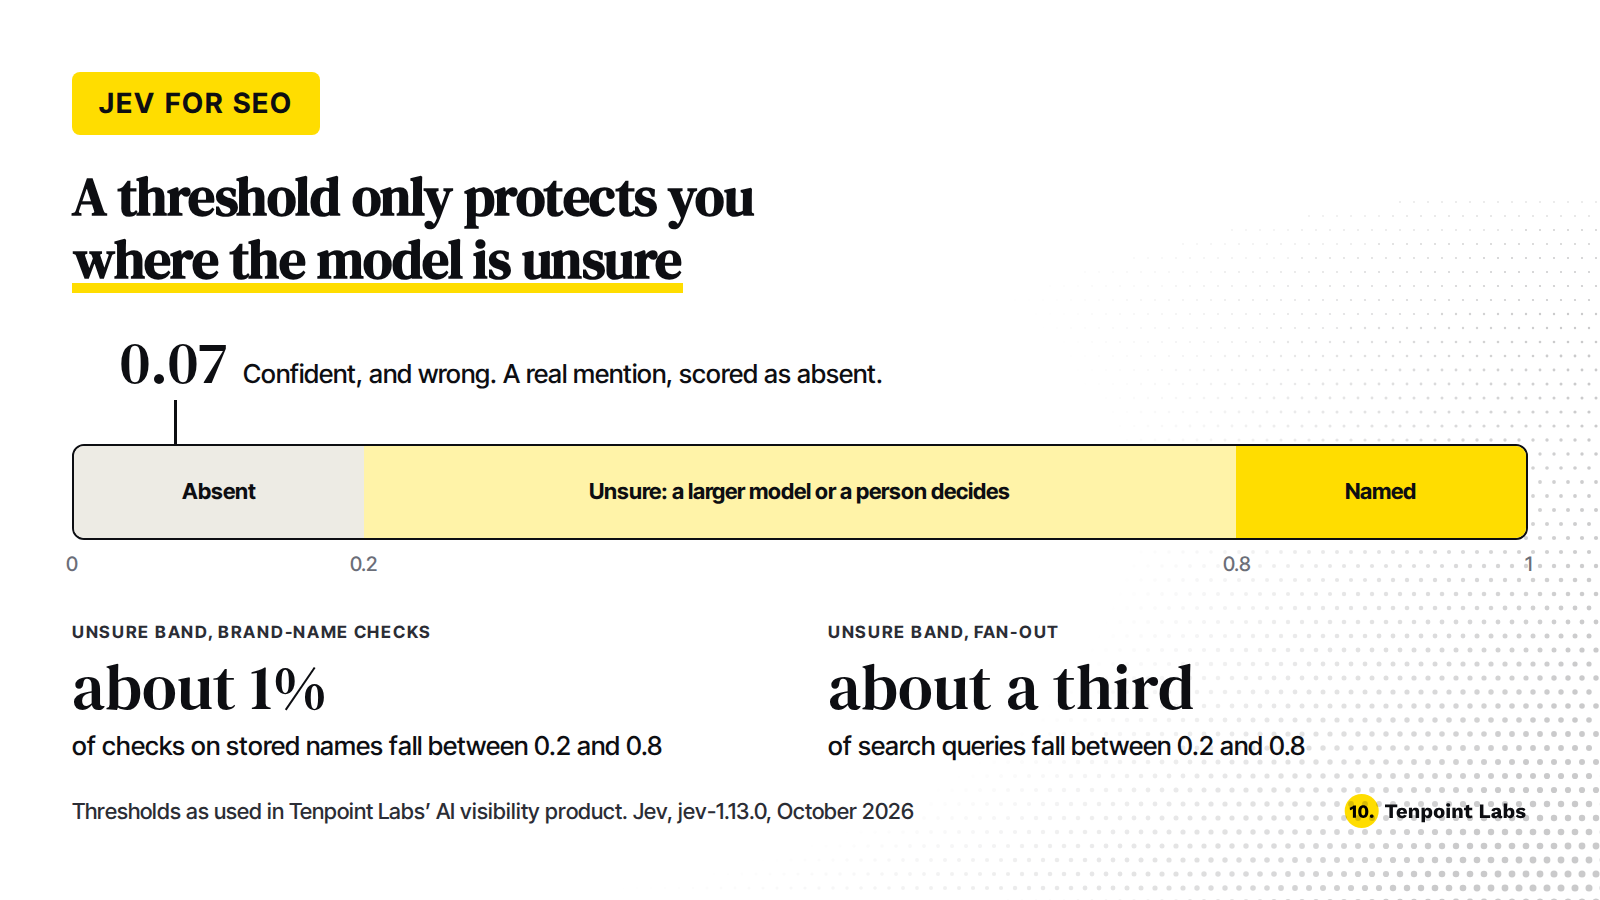
Two cautions come with that approach. A threshold only offers protection where the model is unsure, and the name-form problem described above produced noes that were both confident and wrong and so slipped past every threshold we had. The size of the unsure band also varies a great deal by job - from about 1% of brand-name checks on stored names to about a third of search queries on fan-out.
What does it cost?
The cost is low enough that it stops being a reason to work from a sample. A search query with one question attached ran to about 420 input tokens and an AI answer with its questions to about 1,040, with a median response time near 400 ms.
The better-worded questions are more expensive however. Splitting one question into four or eight raised token use by 2.4 to 4.1 times, which is worth knowing because on search intent that split bought us nothing.
How we tested it
- Blind labels. For each job a reader labelled a sample without seeing any method's answer. The reader was a larger AI model and I then labelled 120 rows myself.
- How far I agreed with the reader: 26 of 30 on brand mentions, 21 of 28 on intent, 14 of 24 on keyword relevance, and 6 of 30 on fan-out. Each result should be read with that in mind.
- Unseen data. The intent and fan-out designs were frozen and then run on five sites they had never seen.
- Client data is described by industry and never named. Examples in the posts come from our own site or are altered, and say so.
FAQs
Can Jev be used for SEO?
Yes, for closed questions about text - whether a brand is named, what a searcher wants, whether a keyword fits a product. It is the wrong tool for writing, counting, date logic and anything a rule already gets right.
Is Jev better than a larger AI model for SEO classification?
On the jobs we tested it was level with or ahead of the larger model or vendor tool it replaced at a fraction of the cost. That held for three jobs and is unproven beyond them.
How much does Jev cost?
TypeSafe lists jev-1.13.0 at $0.042 per million input tokens, with output free. A typical search query with one question uses about 420 tokens.
Does Jev replace an SEO strategist?
It labels and sorts data so that a strategist can see all of it, and the decisions about what to do with that view stayed with a person in every test we ran.
What is the difference between Jev and a regex?
A regex matches patterns in text and costs nothing to run, where Jev judges meaning. Where a pattern is enough - such as spotting your own brand name - the regex is the better tool.
See where your brand stands in AI answers
The first job we gave Jev was counting how often AI engines name a brand. Our Free AI Visibility Audit runs your buyers' questions through the major AI engines and shows who gets named. It will be worth watching how much more of this work small decision models take on in the years to come.